TL;DR
- Announced 13 October 2026 at the China International Industrial Fair: 6 nm, 16x Cortex-A55, 256 TOPS mixed-precision FP4 with no sparsity, up to 128 GB LPDDR5X at 273 GB/s, 40 W per module.
- Both it and the DGX Spark run a 256-bit LPDDR5X bus, so both cap near 20 tok/s on a 27B 4-bit model. The 30 percent decode claim is plausible; the 25 percent prefill claim rests on a quarter of the Spark peak FP4.
- ax-llm does not list the AX8860 yet, Pulsar2 V7.0 ships a Quick Start but no operator support list for it, and the compiled model zoo tops out around 4B.
System Requirements
| RAM | Up to 128 GB LPDDR5X on-package |
| GPU | Axera AX8860 NPU, four cores, Neutron v7 |
| VRAM | 273 GB/s shared bandwidth, 256-bit bus |
Same 128 GB of LPDDR5X. Same 256-bit bus. Same 273 GB/s. A quarter of the FP4 compute, a seventh of the power budget, and a claim that it runs a 27B model faster.
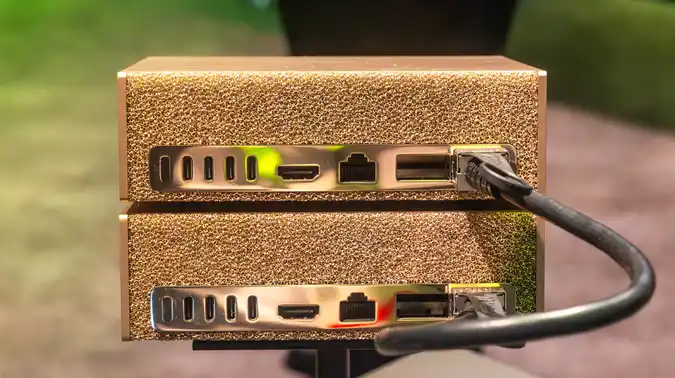
Axera announced the AX8860 series on 13 October 2026 at the China International Industrial Fair in Shanghai. Board partner Sipeed immediately pointed it at NVIDIA's DGX Spark and said its MaixStation machine prefills 25 percent faster and decodes 30 percent faster on Qwen 27B, at roughly half the price.
Two of those numbers are easy to believe. One of them is not. Here is how to tell which, what the chip actually is underneath the comparison, and the state of the software you would need to use it.
What Axera actually announced
Worth separating the vendor's framing from the partner's. Axera positioned the AX8860 as a high-compute edge part for on-site deployment of large models: smart manufacturing, warehousing and logistics, robotics. The DGX Spark comparison came from Sipeed, not from Axera's launch material.
The published figures, all from Axera:
| Property | Value |
|---|
| Process | 6 nm |
| CPU | 16x Arm Cortex-A55 |
| NPU | 256 TOPS mixed precision, native FP4, no sparsity in that figure |
| Memory | Up to 128 GB LPDDR5X on a 256-bit bus |
| Bandwidth | 273 GB/s |
| Power | 40 W per module |
| Interconnect | AXLink cascade plus PCIe 5.0 |
| Video | 64-channel decode, 16-channel encode |
Alongside the chip, Axera showed the Yuanxi A256S module (chip plus memory, you build the carrier board) and single, dual and quad-chip inference cards. Cascading two chips is quoted at 512 TOPS and four at 1,024 TOPS, which are sums of peak numbers rather than measured speedups. One partner, Yuanli Lingji, demonstrated an embodied-AI model on the platform doing connector inspection and industrial insertion tasks, with no performance figures attached.
One spec row gives the chip's real parentage away. 64 channels of video decode and 16 of encode is not what you build for a desktop LLM box. That is a video-analytics SoC, which is exactly Axera's business: it sells AI-ISP and NPU silicon into cameras and industrial vision. The AX8860 is that lineage scaled up until it has enough memory to also hold a language model.
Why 273 GB/s is the same number on both machines
This is the part that gets reported as a coincidence and is not one.
Memory bandwidth is bus width times transfer rate. A 256-bit bus moves 32 bytes per transfer. LPDDR5X at 8,533 MT/s gives 8,533 x 32 = 273,056 MB/s, or 273 GB/s. Any chip that picks a 256-bit interface and that memory speed lands on the same figure. NVIDIA's GB10 did, and so did the AX8860.
| Axera AX8860 | NVIDIA DGX Spark (GB10) |
|---|
| Memory | Up to 128 GB LPDDR5X | 128 GB LPDDR5X (64 GB via OEMs) |
| Bus width | 256-bit | 256-bit |
| Bandwidth | 273 GB/s | 273 GB/s |
| Peak FP4 | 256 TOPS, dense | 1 PFLOP (1,000 TOPS) |
| CPU | 16x Cortex-A55 | 10x Cortex-X925 + 10x Cortex-A725 |
| Power | 40 W per module | 140 W chip TDP, 240 W supply |
Two rows in that table decide everything.
The CPUs are not in the same class. Cortex-A55 is Arm's small in-order core, announced in 2017 and normally used as the efficiency half of a big.LITTLE pair. Sixteen of them is a lot of A55, but it is still sixteen A55s. The Spark pairs ten Cortex-X925 performance cores with ten A725s. If any part of your pipeline runs on the host CPU (tokenizer, sampling, data loading, a Python server), that gap shows up.
The compute gap is roughly 4x. 256 TOPS dense FP4 against NVIDIA's 1 PFLOP. Hold that thought.
The arithmetic that settles the two claims
Decoding a token from a dense model means reading every weight once. So the ceiling is bandwidth divided by the size of the weights, and you can do it on the back of an envelope.
A 27B model at 4 bits is about 13.5 GB of weights. At 273 GB/s:
273 GB/s / 13.5 GB per token = ~20 tokens/s
That is the hard ceiling for a 27B 4-bit model on either machine, because both have the same bandwidth. Add the KV cache and the real figure is lower.
Which makes the decode claim entirely plausible. Beating the Spark by 30 percent on decode does not require better hardware. It requires the other machine to be sitting further below a ceiling they both share, which is a software statement, not a silicon one. A dedicated NPU running a compiled graph can get closer to the memory roofline than a general-purpose stack does.
And it makes the prefill claim the one to interrogate. Prefill is compute-bound: you process the whole prompt in parallel and the limit is arithmetic throughput. Claiming 25 percent more prefill throughput with roughly a quarter of the peak FP4 means claiming something like 5x the efficiency per advertised TOP. That is not impossible, because peak TOPS numbers are marketing and utilisation varies enormously, but it is the figure that needs a disclosed test more than any other.
Neither claim comes with absolute tokens per second, a quantization, a context length, a software version, or measured power. Until it does, it is a relative number against an undisclosed baseline.
The price question is really a memory question
"About half the price of a DGX Spark" is a moving target, because the Spark's price has moved a lot.
| Date | DGX Spark | Price |
|---|
| Oct 2025 | Founders Edition, 128 GB, 4 TB | $3,999 |
| Feb 2026 | Same box, after an 18 percent rise NVIDIA attributed to memory supply | $4,699 |
| Oct 2026 | New 64 GB model, OEM channels only | $4,999 |
| Oct 2026 | 128 GB OEM boxes, reseller listings | $5,660 to $9,097 |
The second-to-last row is the odd one: NVIDIA's answer to expensive memory was a machine with half the memory at more than the original full-memory price.
Here is the catch for Axera. The expensive component in a 128 GB LPDDR5X machine is the 128 GB of LPDDR5X, and it is the same part in both boxes. Axera's silicon is cheaper than a GB10, certainly. But if DRAM is what pushed the Spark from $3,999 to the high four figures, then a competitor carrying an identical memory bill has limited room to be half the price unless it has notably better supply contracts. Treat "half" as an aspiration until there is a listed SKU.
For context on what the same money buys elsewhere, our look at Tenstorrent's TT-QuietBox 2 at $9,999 is the other end of the open-hardware range, and the DGX Spark against Mac Studio and Ryzen AI MAX comparison is where this whole category started.
What you could actually run on it today
Axera deserves real credit here: unusually for a Chinese edge-silicon vendor, the stack is public and permissively licensed. The GitHub organisation has been active since May 2022, carries 145 repositories, and the important ones are BSD-3-Clause.
ax-llm is the LLM runtime, and it is further along than you would expect. It serves an OpenAI-compatible API, adds llama.cpp-style embedding endpoints, caches multiple prefix KV slots so several system prompts do not each re-run prefill, loads layers dynamically to fit small memory pools, drives multiple PCIe cards, and ships Docker images for x86 and aarch64 hosts.
axllm serve /models/<model_dir> --port 8000
curl -s http://127.0.0.1:8000/health
Then the gaps, which matter more than the features right now:
- ax-llm does not list the AX8860. Its supported-chip list is AX650A, AX650N, AX8850N, AX8850, AX637R, AX8190 and AX630C. The new part is absent.
- The existing model packages target the wrong NPU generation. Axera's ready-to-run bundles are built for NPU3 on AX650 and AX8850. The AX8860 is a different architecture, documented as Neutron v7 with four NPU cores and NPU1, NPU2 and NPU4 compile modes. Everything has to be recompiled.
- There is no published operator support list for it. Pulsar2 V7.0 ships a Quick Start for the AX8860, but the operator tables exist for AX650, AX620E, AX615, M57 and AX637 and not for this chip. That list is how you find out whether your model compiles before you buy the hardware.
- The model zoo is small-model shaped. The published builds run to roughly 2B to 4B: Qwen3-VL-4B, MiniCPM5-2B, Qwen3.5-2B, Gemma-4-E4B. Nothing near 27B, which is the size the headline claim is about.
The toolchain itself is a compile-and-quantize flow, not a drop-in runtime. You feed it ONNX, give it a calibration dataset, and it emits an .axmodel:
pulsar2 build --target_hardware AX8860 \
  --input model/mobilenetv2-sim.onnx \
  --output_dir output \
  --config config/mobilenet_v2_build_config.json
Axera says the chip supports vLLM, SGLang and PyTorch. If that is a genuine port rather than a host-side shim, it is the most important thing in the announcement, and it is also the claim with the least public evidence behind it. The repositories visible today point at a bespoke runtime, not those three.
That contrast is the whole argument against this chip and for the Spark. A DGX Spark runs CUDA, so the stack you already know works on it. The AX8860 asks you to re-enter your models through a compiler. When it works it is excellent, and Axera has receipts: there are ready-made NPU packages for the Laya typed-decision models and resources for Frigate NVR detection. But those are vision and classification workloads on last-generation silicon, which is the business Axera is actually in.
Gotchas
- The TOPS figure is unsettled. Axera says up to 256 TOPS. Radxa's spec preview for its own AX8860P board says up to 128 TOPS. Nobody has explained the gap, and it may simply be a different SKU.
- 40 W is the module, not the machine. A four-chip card in the launch photos has four fans and an 8-pin auxiliary power connector. Whatever that card draws, it is not 160 W.
- Cascade scaling is not linear. Sipeed quotes about 80 percent scaling across four units, so 1,024 TOPS is a ceiling, not a throughput.
- Nothing has shipped. Samples are described as a month away and the NPU toolchain for the part as weeks away. Availability is "2026".
- There is a known runtime bug in the PCIe path. ax-llm documents Gemma-4 producing garbled, repeating output on the AXCL PCIe backend while the on-chip backend is correct, traced to numerical divergence in cross-layer shared KV. The fix is to use the on-chip path. If you plan to run a four-card inference server, that is the backend you will be on.
- FP4 native is a quality claim as well as a speed claim. Running weights at 4 bits without a published quality benchmark is the same gap we flagged on Strata's 2-bit speed tables. Fast wrong tokens are still wrong.
Who should care
If you are deploying vision or small-model inference into an industrial setting where 40 W and 64 video streams are the binding constraints, this is aimed squarely at you, and Axera has a track record on that job. A 128 GB far-edge node that also holds an LLM for on-site reasoning is a real product, and that is the pitch Axera made.
If you want a desk machine for open-weight LLM work, wait. Not because the silicon looks bad, but because the chip is not in the runtime's supported list, the operator tables are not published, the model zoo tops out around 4B, and the numbers come without a test configuration. Any of those can change in a month. None of them has yet.
And if you are comparing on price, the more useful exercise is what expert offload already does on hardware you own. A 273 GB/s machine is a 273 GB/s machine whoever makes it.
Sources and further reading
Ten minutes: work out whether this chip could ever help you. Take the model you actually run, multiply its parameter count by the bytes per weight at your quantization, and divide 273 by the result. That is the decode ceiling for every 256-bit LPDDR5X machine on the market, this one included. If your workload is prefill-heavy or batch-heavy you are shopping for compute and the Spark still has four times as much on paper. If it is decode-bound and single-user, you are shopping for bandwidth, and bandwidth is the one number where these two machines are identical.
Not independently tested. We have no AX8860 hardware and there is none to buy. Every performance and price claim above is attributed to Axera or to Sipeed; the DGX Spark figures are NVIDIA's published specifications, the pricing history is from NVIDIA's announcements and a reseller price tracker, and the toolchain and runtime details were read directly from Axera's public repositories and Pulsar2 documentation on the date below.
Date checked: 2026-10-14