TL;DR
- Python prepares and compiles the graphs, then a Rust runtime serves them with no interpreter in the loop
- SM120/SM121 only, so RTX 50 series, RTX PRO 6000 Blackwell and DGX Spark. An RTX 4090 cannot run it
- No published benchmarks: the internal acceptance bar is matching vLLM at concurrency 1, 2 and 4
System Requirements
| RAM | Spark builds run on its unified memory; the four-GPU DeepSeek package wants 256 GiB of host RAM |
| GPU | SM120 or SM121 only: RTX 50 series, RTX PRO 6000 Blackwell, or DGX Spark (GB10). Ada and Hopper are excluded |
| VRAM | One 24 GB-class GPU for Nemotron Bolt 74B-A9B; four 96 GB cards for DeepSeek V4.1 Flash |
NVIDIA put a new inference server on GitHub on Monday. The summary going around is "NVIDIA rewrote vLLM in Rust," and Flare's own design document spends most of a page explaining why that would be a bad idea. The repository is 61% Python by volume. Rust is the part that serves; it is not the part that matters most, and the maintainers say so in writing.
What shipped
Flare is a local inference server for NVIDIA SM120 and SM121 GPUs, Apache-2.0, in the NVIDIA GitHub organisation. The repository became public on 20 October 2026 with 770 commits already on main, so this is a private project opened up rather than a first commit. Commits in the history go back to at least 9 October. As of writing it has 394 stars, 32 forks and 5 open issues, and it is being pushed to several times a day.
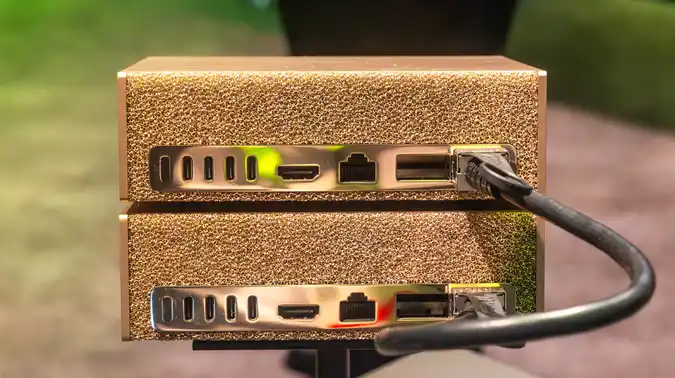
The README states the target plainly: "long conversations, coding agents, and repeated tool use," with the goal of making "the memory, bandwidth, and compute in workstations and compact systems such as DGX Spark go further."
Four claims are circulating about it. Three are exactly right and one needs a footnote.
| Claim | Verdict | What the repo actually says |
|---|
| Built for long chats, agents and tool calls | Correct | Verbatim from the README's first paragraph |
| Plans memory up front | Correct | "Plan buffers and execution capacities ahead of time" |
| FP8 KV cache by default | Correct | "Every recipe defaults to FP8 E4M3 KV storage," including draft-model caches |
| Serves from Rust, no Python | True of the serving process, misleading about the project | Python 7.0 MB of source against Rust's 4.5 MB |
The split that does the work
Flare is two programs. Ignition is Python: it loads a checkpoint with PyTorch and Transformers, tunes kernels through FlashInfer and a library called b12x, runs torch.compile on complete forward passes, captures CUDA graphs, and writes all of it into a signed runtime package. Helios is the Rust runtime that serves that package. By the time Helios starts, compilation and graph capture are finished, so the serving process needs "neither a Python interpreter nor Python callbacks."
That boundary is where the interesting decisions live. Helios owns scheduling, cache pages, admission and request handling; recipes own model computation. The runtime is forbidden from knowing which model it is running, and the rules close the obvious loopholes: no "per-model boolean policy flags, including supports_*, can_*, and default-false opt-ins," and "enums, callbacks, schema names, and metadata fields cannot serve as alternative model allowlists."
Why NVIDIA says Rust is not the headline
This is the part nobody quoting the launch has read. From docs/core-design.md:
"A wholesale 'vLLM in Rust' rewrite is a poor trade when it severs access to the Python model and kernel ecosystem. It takes on a much larger obligation than building a scheduler. It must continually reproduce model architectures, checkpoint conventions, quantization rules, multimodal processors, compiler integrations, and numerical fixes."
And, a few paragraphs later: "Language choice alone also says little about GPU execution. A Python-defined model can launch compiled kernels and replay captured graphs; vLLM itself uses CUDA graphs. Translating host code does not reduce the weights read by a GEMM, fuse an attention kernel, or repair an inefficient layout."
So the design is deliberately not a rewrite. Python keeps everything it is good at and gets dropped before the first request arrives. If you were expecting the usual Rust-beats-Python throughput story, the vendor is telling you in advance not to.
Who can actually run this
Here is the sharp edge. SM120 is GB202 and its siblings, meaning the RTX 50 series and the RTX PRO 6000 Blackwell cards. SM121 is GB10, which is DGX Spark. An RTX 4090 is Ada and not invited. Neither is an H100, which is SM90, nor a B200, which is SM100. This is a consumer-and-workstation Blackwell engine, and that narrowness is the stated point: "Discrete-GPU measurements cannot establish those properties on Spark."
The two prepared packages published so far show what that means in practice, and they are very far apart.
| Qwen3.8 Flash Next | DeepSeek V4.1 Flash 1017 |
|---|
| GPUs | One | Four SM120 at 96 GB each |
| Hardware revisions | gb10 (DGX Spark) and gb202 | gb202 only |
| Checked on | Spark and RTX PRO 6000 | Four RTX PRO 6000 Blackwell Workstation |
| Concurrency | Up to 16 | 32 |
| Context limit | Model default | 1,048,576 tokens per request |
| Disk | Package only | About 515 GB across nine files |
| Host RAM | Spark: keep tables on disk | At least 256 GiB |
| Status | Labelled "alpha-quality," community preview | Serving checks completed |
If you own a DGX Spark, the Qwen package is your entry point and it is explicitly alpha. If you want the DeepSeek build, you need four 96 GB workstation cards, a quarter of a terabyte of RAM and half a terabyte of disk. "Local" here means "not in somebody else's datacenter." It does not mean cheap.
The six recipes
Flare only runs models someone has written a recipe for. Today that is six, and the list tells you who this is aimed at.
| Recipe | Checkpoint | Shape |
|---|
nemotron-bolt-24gb | NVIDIA-Nemotron-3.5-Bolt-74B-A9B-24GB | One GPU, images, LiLiCorr drafting |
qwen3.8-27b | nvidia/Qwen3.8-27B-NVFP4 | One GPU, text only |
qwen3.8-flash | Qwen3.8 Flash Next | TP1 and TP2, 5 MTP draft tokens |
deepseek-v4.1-flash | deepseek-ai/DeepSeek-V4.1-Flash-1017 | TP4, images, DSML tool calls |
deepseek-v4-flash | DeepSeek-V4-Flash-Vision-Exp-lossless-CSF | TP2 or TP4, vision |
mimo-v2.6-pro-mopd | XiaomiMiMo/MiMo-V2.6-Pro-MOPD | TP8, text and images |
A Nemotron 74B-A9B on a single 24 GB-class GPU is the headline capability, and it comes from the same family as Nemotron 3.5 Super VL. The DeepSeek V4.1 Flash 1017 recipe is the one to watch, because NVIDIA is shipping first-class support for a Chinese lab's MIT-licensed model inside its own serving stack.
How the memory trick works
The reason these models fit at all is that Flare refuses to put everything in VRAM. Qwen3.8 Flash Next has a 26.8 GiB n-gram embedding table; Flare reads the rows it needs from disk by default, on every GPU, and only --embedding-table-storage ram moves it into host memory. DeepSeek V4.1 Flash has 188.8 GiB of Engram tables, partitioned by hash head across the four TP ranks, read on demand through bounded direct I/O.
If that sounds familiar, it is the same bet Colibri made with MoE experts and Strata made with a three-tier split. The difference is that Flare plans the whole budget as one number: on DGX Spark, CPU and GPU allocations come from the same DRAM, so the docs point out that "a host copy of a GPU cache therefore consumes the same physical capacity; calling it an offload tier creates no additional memory." That is the correct way to think about unified memory and almost nobody writes it down.
Running it
There is a published container, which is much shorter than building from source. For Qwen on a Spark, with the embedding table left on disk as the docs recommend:
docker run --rm -it --user "$(id -u):$(id -g)" \
  --gpus 'device=0,capabilities=compute' --ulimit memlock=-1:-1 \
  -p 127.0.0.1:8000:8000 \
  --mount "type=bind,src=$PWD/flare-cache,dst=/cache" \
  --mount "type=bind,src=$PWD/flare-state,dst=/state" \
  --mount "type=bind,src=$HOME/.cache/huggingface/token,dst=/hf-token,readonly" \
  ghcr.io/local-inference-lab/flare:latest \
  run local-inference-lab/Qwen3.8-Flash-Next-FLARE \
  --gpus 0 --cache-dir /cache --token-file /hf-token \
  --embedding-table-storage disk --embedding-table-cache-size 1GiB \
  --trust-store /state/trust.toml --port 8000
Flare picks the gb10 or gb202 revision for your GPU itself. You will be asked to accept the publisher and model licence on first use, and the writable state directory remembers that.
Building from source is a real build, not a pip install:
sudo apt-get install build-essential cmake ninja-build pkg-config \
  protobuf-compiler libssl-dev python3-dev liburing-dev
uv sync --locked --extra prepare --extra test
cargo build --release --manifest-path flare/Cargo.toml
Preparing your own package then needs the CUDA toolkit with nvcc and CUPTI, and it must run on the same GPU architecture you intend to serve on.
There are no benchmarks, and the acceptance bar is parity
Flare publishes no performance numbers at all. Not one tokens-per-second figure in the README, the core design, or the performance guide. What it publishes instead is the standard it holds itself to, and that is more revealing than a chart.
From the acceptance criteria: "Flare must match or improve end-to-end TTFT, inter-token latency, and completed-work throughput across the required local workloads at concurrency 1, 2, and 4." A commit from 9 October, eleven days before the repository went public, is titled "Require matched vLLM serving performance for acceptance."
Two things follow. First, NVIDIA's internal bar is matching vLLM, not beating it, which fits a project whose value proposition is memory behaviour rather than raw speed. Second, concurrency 1, 2 and 4 is the whole design target. This is tuned for one developer and their agents, not for a serving fleet.
The docs also do the physics for you. For the DeepSeek recipe at decode batch one, weight traffic is about 6.9 GB per token, and "at the target GPU's 1.79 TB/s this gives a bandwidth bound near 3.9 ms per token." That is a ceiling of roughly 256 tokens per second that no amount of Rust can move, which is rather the point the design doc was making.
One standard worth stealing for your own projects: "an aggregate win does not erase a workload regression."
The file that tells coding agents to go away
The first line of the README, above everything else, is a note to robots: "Coding agents: skip this README and read AGENTS.md directly."
What they find there is not a welcome mat. AGENTS.md is a rejection manifesto. Every contribution "must address an explicit maintainer request, a demonstrated defect, a measured performance or memory problem, or inaccurate documentation," and then, explicitly: "Hypothetical future consumers, agent-generated suggestions, and lint findings alone do not establish a need for a change."
It goes further. Reviewers are told to recommend rejection and "not rescue it by adding an opt-in, weakening the rule, expanding its scope, or promising future cleanup." Tests that pass are not sufficient: "source-text checks and mocks that bypass the behavior cannot establish runtime correctness." Neither is a win: "a feature request, passing tests, or a performance gain does not waive an architectural invariant." Every commit requires a design acknowledgment enforced by a commit-msg hook, and a rejected acknowledgment "requires reading that document and reviewing the staged change before retrying; do not treat the rejection as a formatting repair." New captured-graph operation families need prior approval from a single named project owner.
We have been tracking agent scaffolding all month, most recently Google's Harness2, which optimises the harness around a model. Flare is the other side of that coin: a major vendor repository whose governance is written on the assumption that agents will arrive with plausible, well-tested, unnecessary patches. Whatever you think of the tone, it is the first contribution policy we have seen that treats "an agent suggested it" as a reason for extra scrutiny rather than less.
The timing was not a coincidence
Four days before Flare went public, DeepSeek created the repository for DeepInfer, its own production inference framework, and opened it on 20 October. Two inference engines, two of the most consequential labs in the field, both Apache-2.0, one week. They could not be more different.
| Flare | DeepInfer |
|---|
| Hardware | SM120/SM121 (RTX Blackwell, DGX Spark) | SM100 Blackwell, Huawei Ascend 950 |
| Target | Workstations and compact systems | Large-scale production serving |
| Concurrency design point | 1, 2 and 4 | Production batch load |
| Models | Six recipes | DeepSeek-V4.1-Flash only |
| Relationship to vLLM | Deliberately not a rewrite | Names vLLM as its original foundation |
| Serving | Interactive HTTP and SSE | Offline batch; online serving needs more parts |
| Stars | 394 | 17,162 |
| Open issues | 5 | 179 |
DeepInfer has 43 times the stars of a repository from NVIDIA, which tells you something about where attention sits right now. It is also the smaller codebase. Flare's checkout is roughly three and a half times larger.
Limitations and gotchas
The runtime package format is a one-way door. Those .safetensors files "cannot be loaded directly by Transformers, vLLM, SGLang, or llama.cpp." They contain compiled kernels and captured graphs, not just weights.
Packages are also fixed at preparation time in ways that will catch you out. "Each tensor-parallel size requires a separately prepared package; a TP2 package cannot be loaded as TP1." Image concurrency is baked in too, and changing it "requires exporting the package again." You can lower text concurrency at load time but not raise it.
Known gaps are stated honestly, which is worth crediting: "Qwen TP1 and TP2 and GLM TP4 have been exercised end to end; Qwen TP4 still requires model validation." Strict function schemas are unsupported, which matters if your agent needs guaranteed JSON shapes. Video is not prepared for Nemotron, audio is not prepared for MiMo.
Watch the licences separately from the engine. Flare is Apache-2.0, but the prepared packages are not uniform: the DeepSeek runtime carries MIT, while the Qwen base checkpoint sits under a custom lil-license-1.0. Check the package, not the server.
Who should use it
Try it today if you have a DGX Spark and a tolerance for alpha software. The Qwen package with the embedding table on disk is a genuinely novel thing to have running on a desk-side box, and the Docker path means you are twenty minutes from a token.
Watch it if you run RTX 50-series or RTX PRO 6000 hardware. The recipe list is the constraint, not the engine, and recipes are landing fast.
Stay on vLLM if you need breadth, which NVIDIA agrees with: vLLM "covers a much broader range of models, hardware, and deployment patterns." If your GPU is Ada, Hopper or datacenter Blackwell, that is not a preference, it is the only option.
Read it even if you never run it when you care about how serving engines are built. docs/core-design.md is 100 KB of unusually candid engineering reasoning about memory topology, cache ownership and why not to rewrite things in Rust. It is better reading than most papers on the subject.
Sources and further reading
Your under-ten-minutes move: run nvidia-smi --query-gpu=name,compute_cap --format=csv on the machine you were hoping to use. If it does not say 12.0 or 12.1, Flare will not serve a single token on it, and you have saved yourself an evening.
Tested on: not independently tested. Every figure above was read from the Flare repository, its design documents, the two prepared Hugging Face packages and the GitHub API on the date below. Flare publishes no performance benchmarks; the bandwidth bound quoted is NVIDIA's own calculation, and the hardware requirements are from the package model cards. Repository counts move daily.
Date checked: 2026-10-21